Key Specifications
- GPU: NVIDIA H200 Tensor Core GPU
- Architecture: NVIDIA Hopper
- GPU Memory: 141GB HBM3e per GPU
- Memory Bandwidth: Up to 4.8TB/s per GPU
- FP8 Tensor Performance: Up to 3,958 TFLOPS with sparsity
- Interconnect: NVIDIA NVLink / PCIe Gen 5
- MIG Support: Up to 7 GPU instances
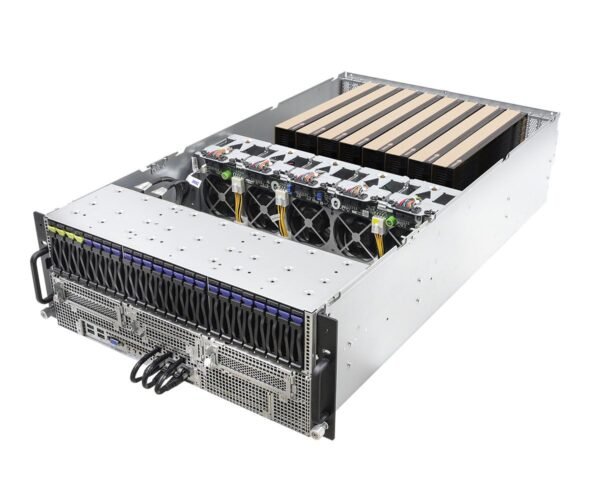
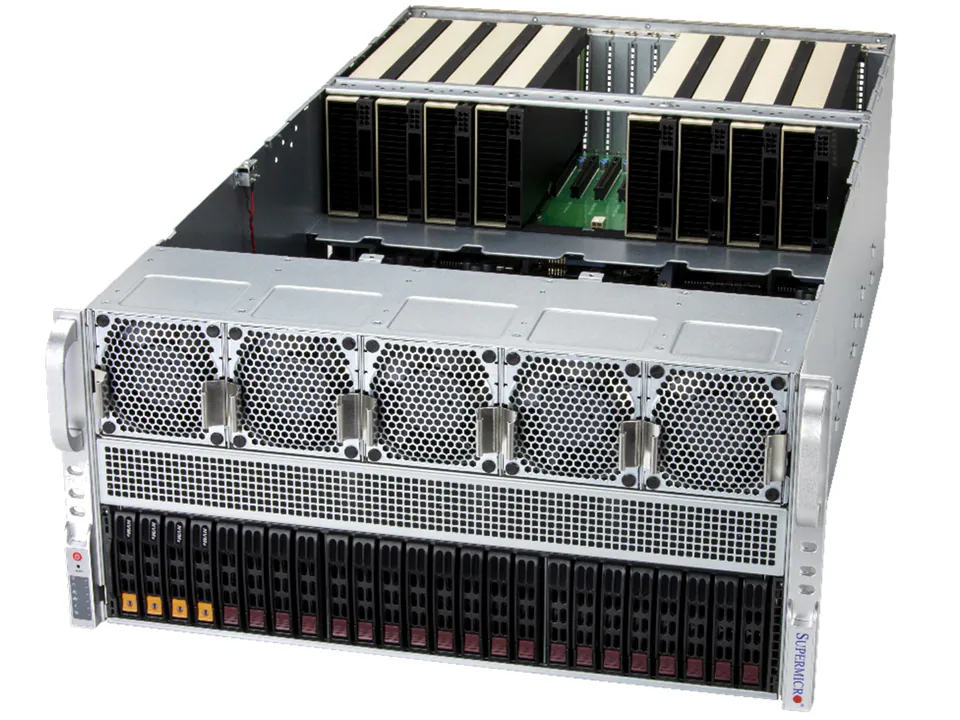
- Typical Server Configurations: 4-GPU or 8-GPU
- Deployment: AI data center, private cloud, GPU cluster and colocation environments
Built for Large AI Models
The H200’s 141GB HBM3e memory is one of its biggest advantages for modern AI workloads. Compared with H100, NVIDIA states that H200 provides significantly more GPU memory and higher memory bandwidth, helping improve performance for large-model inference and other memory-intensive workloads.
Typical workloads include:
- Large language model training
- LLM inference
- Generative AI
- Multimodal AI
- Retrieval-Augmented Generation
- AI agents
- Scientific computing
- HPC
- Simulation
- Enterprise AI infrastructure
Available H200 Server Configurations
We can provide H200 GPU server solutions based on workload, power, memory and deployment requirements.
Typical configurations include:
- 4 × NVIDIA H200 GPU Server
- 8 × NVIDIA H200 HGX Server
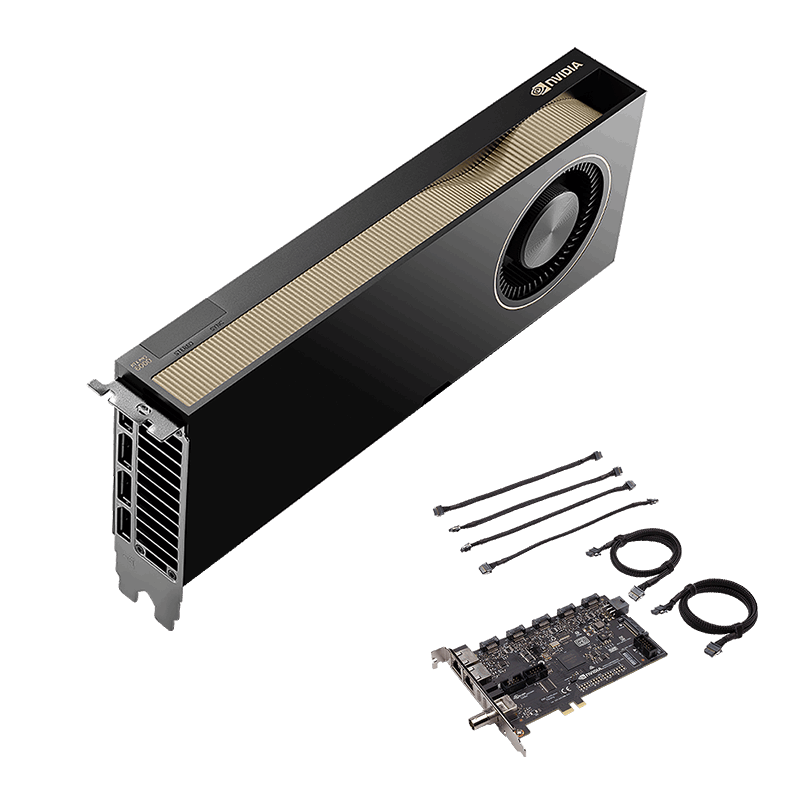
- H200 NVL server configurations
- Custom CPU, RAM and NVMe storage
- High-speed Ethernet or InfiniBand networking
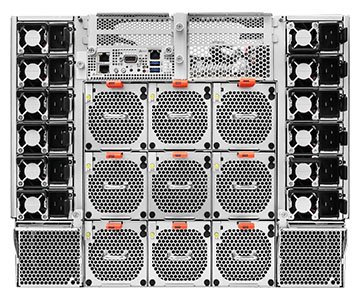
- Complete rack-ready AI server systems
For an 8-GPU HGX H200 system, total GPU memory can reach approximately 1.1TB of HBM3e, with aggregate GPU memory bandwidth of up to 38.4TB/s.
H200 for AI Inference
H200 is particularly well suited for AI inference because larger GPU memory allows larger models and batch sizes to remain in GPU memory.
NVIDIA reports that H200 can provide substantial inference improvements over H100 in selected large-model workloads, including Llama 2 70B and GPT-3 175B benchmarks.
Buy and Host Your H200 Server With Us
Desert Eagle AI can provide both H200 AI server hardware and U.S.-based GPU server hosting.
You can purchase an H200 server from us and:
- Ship it to your own facility
- Deploy it in your existing data center
- Host it directly in our U.S. facility
- Use our colocation, power and network infrastructure
- Request remote hands and on-site hardware support
This allows customers to source and deploy their AI infrastructure through one provider.
Buy Your GPU Server. Host It With Us.
H200 GPU Server Colocation
Already own an H200 server?
We can support compatible GPU server colocation deployments with:
- Rack space
- Power
- Network connectivity
- Public IP availability
- Remote hands
- Server installation
- Hardware troubleshooting
- Component replacement
- Ongoing infrastructure support
Contact us with your server model, GPU quantity, power requirements and deployment location for availability and hosting options.
Ideal Customers
The NVIDIA H200 AI GPU Server is suitable for:
- AI startups
- LLM companies
- GPU cloud providers
- Enterprise AI teams
- Research labs
- Universities
- HPC organizations
- Generative AI companies
- Robotics and Physical AI companies
- Private AI infrastructure deployments